AutoData: Agentic Search for Pre-training Data Selection

AutoData: How Agentic Search Over Algorithms Could Replace Hand-Tuned Data Curation
AutoData emerges as an agent that searches directly over executable selection algorithms for pre-training data selection. Not a minor update, not another tweak to deduplication scripts—it reframes LLM data curation as an agentic optimization task over executable algorithms. Within an overnight search, AutoData discovers a selection algorithm that outperforms existing human-designed curation pipelines. The discovered recipe transfers to larger scales. If this holds, manual data curation might be finished.
The Problem: Why Data Curation Is Broken
Right now, LLM pre-training data gets curated through heuristic filters and fixed-domain weighting. Deduplication, quality classifiers, and hand-tuned ratios. These methods are rigid. Brittle. Built on intuition, not empirical feedback. Minor tweaks to data composition can swing downstream performance by double-digit percentages. Proxy models are sensitive to data mix—small adjustments lead to massive variations.
Human-designed pipelines don’t adapt. They’re static snapshots of what worked once. Weight optimization over fixed domains, like DoReMi’s approach, still relies on predefined buckets. It ignores complex feature interactions. Maybe high-perplexity code data improves reasoning—but only when balanced with low-perplexity text. A human curator might miss that. AutoData won’t.
The Shift: From Weight Optimization to Algorithm Search
Here’s the core insight: instead of optimizing weights over fixed domains, AutoData searches over executable algorithms. Not static ratios—programs that dynamically score, stratify, and select data based on learned rules. The search space includes:
- Scoring functions: "Select data with high perplexity" or "prioritize samples with low redundancy. "
- Stratification rules: "Balance by topic" or "ensure diversity in length. "
- Stochastic selection: "Include 10% of low-quality data to avoid overfitting. "
This space is richer than weight optimization. DoReMi optimizes domain weights but doesn't allow conditional logic. AutoData does. It’s not just tuning knobs. It’s discovering the mechanism behind effective data selection.
How AutoData Works: The Agentic Loop
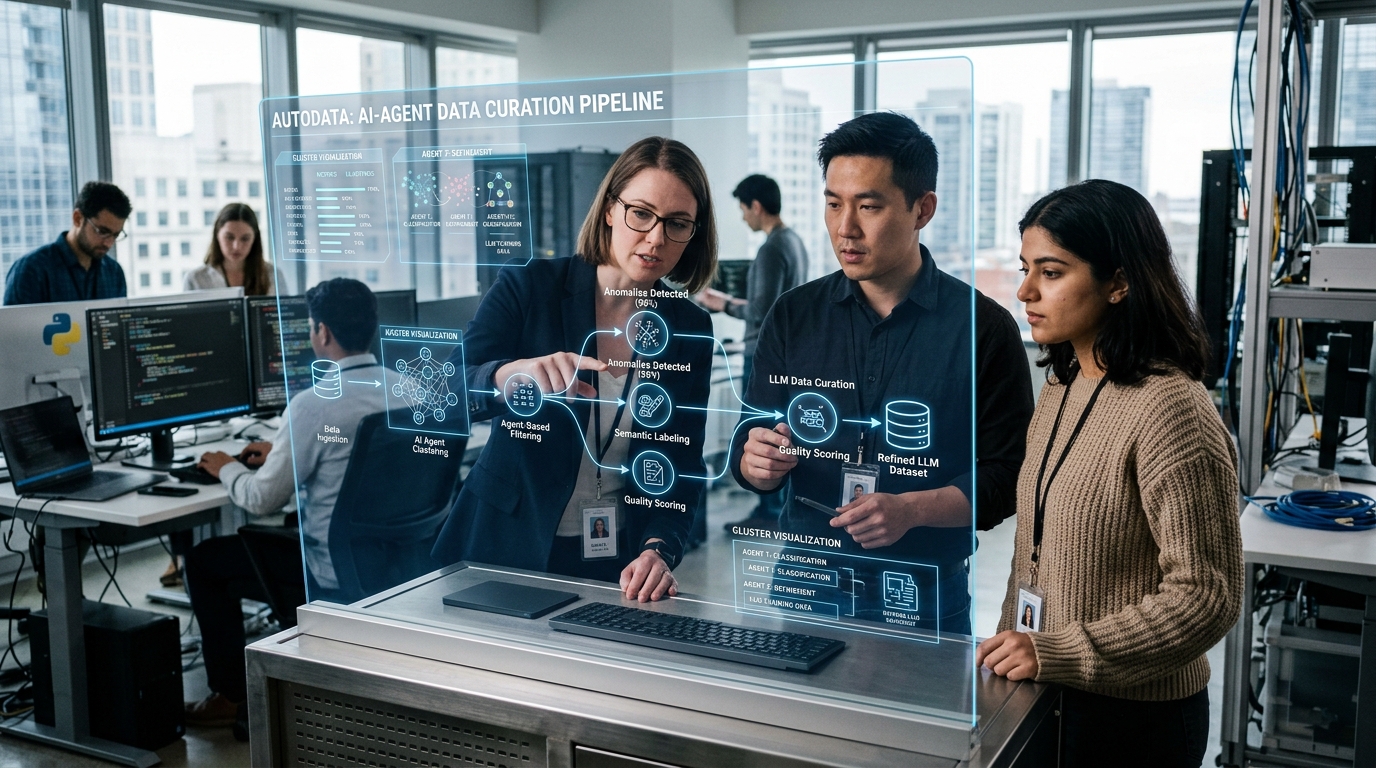
The system starts with a simple algorithm and iteratively refines it using feedback from a proxy model. A smaller, faster-to-train model standing in for the full-scale target. Here’s the loop:
- Generate candidates: AutoData proposes new selection algorithms by mutating or recombining existing ones.
- Evaluate on proxy: The proxy trains on data selected by each candidate algorithm. Performance gets measured on CORE, a benchmark for data quality.
- Update search: The best-performing algorithms are kept. The process repeats.
The critical innovation? AutoData discovers feature interactions automatically. It might learn high-perplexity code data improves reasoning—but only when balanced with low-perplexity text. No human priors. The system infers what matters from the proxy’s feedback.
Within an overnight search, AutoData discovers a selection algorithm. That suggests feasibility without massive resources. A big deal. If this scales, advanced data curation could become accessible to teams without Google-level budgets.
The Results: Outperforming Human Curation
AutoData discovers a selection algorithm that outperforms existing human-designed curation pipelines. The winning recipe isn't just a better weight mix. It’s a dynamic, executable rule combining scoring, stratification, and stochasticity. The brief doesn’t specify the exact algorithm, but examples of what it might look like include:
- "Prioritize data with high signal-to-noise ratio, but include 5% of low-quality samples to avoid overfitting. "
- "Balance by domain, but apply a perplexity filter to code data. "
- "Sample 20% of data randomly to ensure diversity. "
The most compelling part? The discovered recipe transfers to larger scales. That’s non-trivial. Many methods overfit to the proxy’s quirks. AutoData’s approach seems to generalize. This suggests the system isn’t memorizing patterns—it’s learning principles of effective data selection.
Why This Matters: Data Engineering as an ML Problem
AutoData treats data engineering as an agentic ML problem, not a manual or heuristic-driven task. Massive implications:
- Reduced reliance on experts: If selection algorithms can be discovered automatically, fewer domain specialists are needed to curate training data.
- Faster iteration: Teams could run AutoData-like searches for every new model or dataset, rather than reusing stale heuristics.
- Better performance: Even small improvements in data quality can lead to outsized gains in downstream tasks.
The potential stretches beyond pre-training. Imagine applying this to:
- Fine-tuning: Dynamically selecting data for task-specific adaptation.
- Domain adaptation: Automatically curating data for new languages or modalities.
- Synthetic data generation: Discovering algorithms to filter or reweight generated data.
There’s also the possibility of continuous data curation. Data selection evolving alongside the model. Instead of a one-time curation step, data selection becomes a living part of the training pipeline.
The Catch: Challenges and Open Problems
This isn’t a silver bullet. Real challenges remain:
- Computational cost: The search runs overnight, but scaling to larger proxy models or more complex algorithms could get expensive. If this needs a cluster, adoption might be limited.
- Interpretability: Discovered algorithms may be hard to explain. If AutoData learns specific selection rules, that's useful—but why do they work? Without interpretability, safety-critical adoption could stall.
- What if the proxy’s quirks lead to suboptimal algorithms at scale?
- Human-in-the-loop: Could AutoData combine with human feedback without sacrificing performance?
The Competition: How AutoData Compares to Other Approaches
AutoData isn’t the first attempt to automate data curation, but it’s the most ambitious. Here’s the landscape:
Weight optimization (DoReMi): Optimizes ratios over fixed domains but lacks dynamic logic. AutoData’s search space is far richer.
- Reinforcement learning for data selection: Some prior work uses RL, but it’s typically limited to simple policies. AutoData’s search over algorithms allows combinatorial and conditional logic.
- Heuristic pipelines (MassiveText, The Pile): Human-designed rules are static. They don’t adapt to model feedback. AutoData’s approach is learned, not designed.
The key advantage? AutoData discovers the selection strategy. It doesn’t rely on human intuition or fixed heuristics. It infers what works from data.
What’s Next: The Road Ahead for Agentic Data Curation
Immediate next steps:
- Replication and scaling: Will other labs reproduce these results? Can the approach work for larger models or different modalities—vision, speech?
- Integration with existing pipelines: Can AutoData bolt onto current curation workflows, or does it need a ground-up redesign?
- Benchmarking: How does it perform beyond CORE? Does it improve downstream task performance—MMLU, GSM8K?
Longer-term implications are wild:
- Fully automated data engineering: Could future LLMs train with zero human-designed data curation? AutoData hints at this possibility.
- Self-improving data curation: Imagine models iteratively refining their own training data, leading to compounding improvements over time.
- Democratization: If data curation becomes an ML problem, smaller teams could compete with the Googles of the world.
There’s a wildcard: could AutoData enable meta-learning for data selection? Could we train a model that generalizes data curation across tasks?
The Big Picture: A Paradigm Shift?
This feels like more than an incremental improvement. Most LLM progress comes from scaling compute or model size. AutoData suggests data engineering could be the next frontier. If agentic systems handle curation, it could democratize LLM training, reduce reliance on experts, and unlock better performance at scale.
But let’s not get ahead of ourselves. Open questions remain:
- Is this just parameter tuning for data, or does searching over algorithms truly unlock new capabilities?
- Will interpretability challenges limit adoption in safety-critical settings?
- How sensitive is AutoData to the proxy model’s architecture or training data?
The most interesting implication? AutoData hints at a future where data selection is learned, not designed. That could change how we build AI. But for now, the biggest question is whether this scales beyond the initial results. If it does, we might be witnessing the end of manual data curation.
Sources
Key Takeaways
- The evolution of Blog continues to accelerate rapidly.
- Experts like Auto Bot suggest staying informed on these specific developments.
- Consider the broader implications for the tech industry moving forward.