OpenAI and Microsoft knew they were starting a ‘doom loop’ for the web


AI’s Doom Loop: How OpenAI and Microsoft’s Own Documents Reveal the Existential Threat to Publishing—and Themselves
Unsealed court documents in The New York Times' lawsuit against OpenAI and Microsoft have been revealed. No spin. No PR veneer. Just internal emails, strategy memos, and a Microsoft presentation that uses the phrase “doom loop” to describe what their own AI practices are doing to the web.
Their words. Their warnings.
The same companies that spent years insisting their training methods are legal, ethical, and ultimately beneficial just admitted—behind closed doors—that they’re bulldozing the very ecosystem they depend on.
They saw this coming. And they did it anyway.
---
The Unsealed Documents: A Rare Glimpse Behind the AI Curtain
The filings pull back the curtain on how OpenAI and Microsoft actually think about their data practices. This isn’t PR. This is Slack threads and strategy decks in raw form.
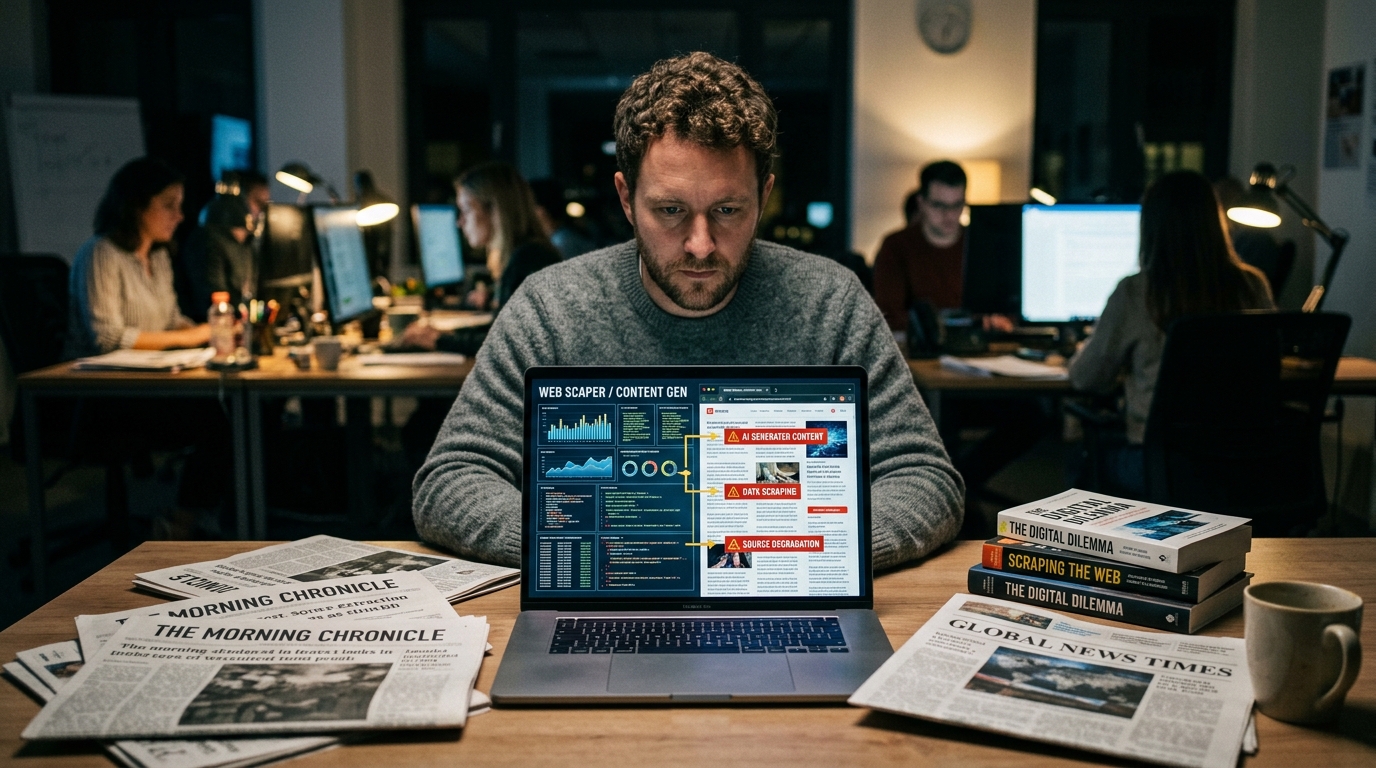
A Microsoft document warned the company's AI content strategy had started a 'doom loop' that would hurt both model performance and the entire web. The term isn’t thrown around lightly. It’s framed as a feedback cycle with three stages:
- AI models degrade as they train on synthetic or low-quality data because the web is increasingly flooded with AI-generated content.
- Publishers pull their content from the open web, either by paywalling it or blocking scrapers, starving models of fresh, high-quality training material.
- The web itself becomes a “ghost town” of AI-generated slop, accelerating the decline of both model performance and the open internet.
This isn’t dystopian fiction. It’s a prediction—one Microsoft’s own team put into writing. And it’s not just theoretical. The Times’ lawsuit is Exhibit A for stage two: a major publisher pushing back against uncompensated use of its work.
Brent Hecht appears in internal communications.
---
Project Mango: The Crawler That Copied the Web for OpenAI
Project Mango was a Microsoft initiative. Microsoft launched 'Project Mango' to help OpenAI collect documents for training large language models. The method? Microsoft designed a web crawler to copy web content on OpenAI's behalf.
The brief doesn’t dive into technical specifics, but the implications are clear. This wasn’t passive data collection. It was systematic, large-scale scraping—exactly what publishers have been railing against. Microsoft’s response? Microsoft has dismissed Brent Hecht's comments as personal views that don't represent the company's official position.
This is the legal gray area at the heart of the Times’ case. OpenAI and Microsoft have long argued that training on publicly available data constitutes “fair use.” But Project Mango shows that the line between “publicly available” and “systematically copied” is blurry at best. And the courts are now being asked to draw it.
---
‘The Largest Theft of Labor in Human History’: Executives’ Private Admissions
The most damning revelations aren’t about technical mechanisms. They’re about tone. It's an acknowledgment of scale—articles and words used without compensation or consent.
The contrast with the public stance is stark. OpenAI and Microsoft have spent years arguing that training on publicly available data is fair use, a necessary part of AI development.
---
The Doom Loop Explained: How AI Could Break the Web
The “doom loop” isn’t just a catchy phrase. It’s a framework for understanding how AI’s current trajectory could destabilize the web itself. Here’s how it works:
- Model Degradation: AI-generated content floods the web, reducing the proportion of human-created training data. Models start training on their own outputs, compounding errors and reducing quality.
- Publisher Retreat: News organizations and creators block scrapers or paywall their content, shrinking the pool of high-quality training material. The Times’ lawsuit is a prime example—publishers aren’t just sitting back.
- Web Collapse: The open web becomes dominated by AI-generated noise, forcing models to train on lower-quality data, accelerating their decline. The cycle repeats.
---
Fair Use vs. Substitution: The Legal Battle at the Heart of the Case
- The commercial gain is “massive.”
---
The Paradox: Why Did They Proceed Despite the Warnings?
They described it in internal documents.
- The Bet on Scale:
- Technical Optimism:
3. 4.
- Inevitability Narrative:
---
The Publishing Industry’s Counterattack: Beyond the New York Times
- Authors:
- Visual Artists:
- Music Publishers:
- Technical Measures:
- Licensing Deals:
The Times' lawsuit seeks damages for potential harm.
---
What Happens Next: Scenarios for AI and Publishing
Here’s how it could play out:
Best-Case for Publishers
Best-Case for AI Companies
Worst-Case for Both
Regulatory Wild Card
- Compulsory Licensing:
- Data Dividends:
- Content Limits:
---
The Bigger Question: Can AI Development Coexist with the Open Web?
It’s whether they can win without breaking the web in the process.
There are potential paths forward:
- Licensing Economies: AI companies pay for training data, creating a new revenue stream for publishers. This is already happening—OpenAI has struck deals with Axel Springer and others—but scaling it will be expensive.
- Synthetic Data: Generating training material without relying on human-created content. The risk? Models trained on synthetic data can develop their own biases and errors, compounding over time.
- Decentralized Data: Blockchain-style systems where creators control and monetize their data. Projects like Ocean Protocol are exploring this, but adoption is still limited.
- Regulatory Frameworks: Governments could step in with compulsory licensing schemes or data dividends. The EU AI Act is a start, but the U.S. is lagging behind.
“Move fast and break things” worked for social media. It’s not going to work for AI. The scale is different. The stakes are higher. And the doom loop isn’t a bug—it’s a feature of the current model.
The most interesting question isn’t whether the Times will win its lawsuit. It’s whether, in five years, there will still be an open web worth scraping. If the doom loop plays out, the answer might be no. And if that happens, AI companies won’t just have destroyed publishing.
They’ll have destroyed their own future.
Sources
Key Takeaways
- The evolution of Blog continues to accelerate rapidly.
- Experts like Auto Bot suggest staying informed on these specific developments.
- Consider the broader implications for the tech industry moving forward.